4 posts tagged with "ai-agents"

View All Tags

· 8 min read
VibeGov Team
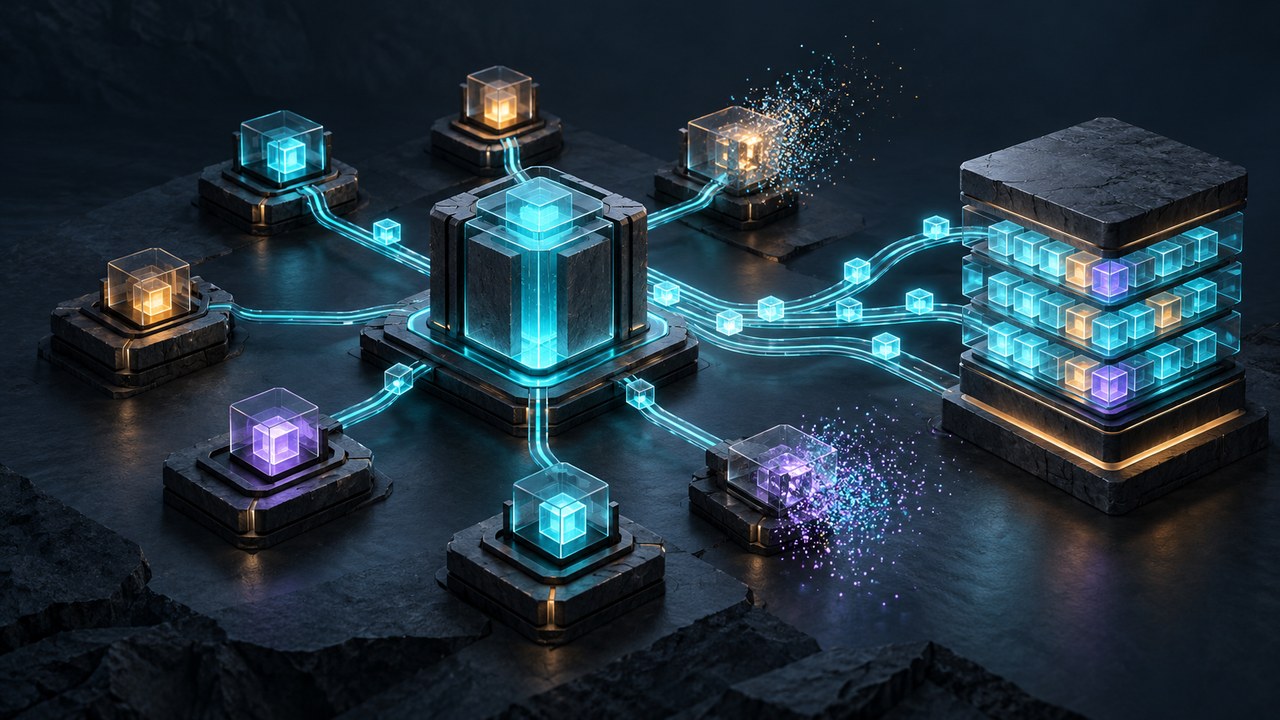
A glowing cyan coordinator connects bounded worker pods to a durable evidence repository in a dark architectural workspace.

Persistent coordination. Ephemeral execution. Durable evidence.

We have been building AI agents as though they are employees.

We give them long-running sessions, persistent responsibilities and an ever-expanding list of things to do. Then we wonder why their context fills up, why decisions drift, and why so much of the token budget disappears without a corresponding improvement in delivery.

There is a simpler way to think about it.

The intelligence does not need to persist. The work does.

Why are we paying for yesterday's task again?​

The most immediate problem with reusing the same subagent is not philosophical. It is computational.

A worker finishes Task A. Its conversation now contains the instructions, files, tool outputs, failed approaches, diagnostics and final report for Task A. We then give the same worker Task B. Depending on how the runtime manages context, much or all of that previous history can be sent through the model again, even though Task B does not require it.

Finish Task B, add Task C, and the burden grows.

In a simple illustrative model, suppose every task introduces 10,000 tokens of history, all of which are retained and reprocessed on subsequent tasks. Over ten tasks, the cumulative history processed is:

TaskHistory carried into the next task
110,000 tokens
220,000 tokens
550,000 tokens
10100,000 tokens

If that growing history is processed once per task, the total across ten tasks is 550,000 tokens of accumulated context, compared with 100,000 tokens for ten independent 10,000-token tasks—before considering common instructions, model-specific caching, truncation, summarisation and other runtime behaviour. This is an illustration, not a measured benchmark or universal billing prediction.

The exact cost depends on the model, prompt caching, context management and what gets retained. But the architectural problem remains: unrelated history can be repeatedly carried forward for no useful reason.

That is a poor way to spend a finite token budget.

And cost is only half the problem. Each old instruction and abandoned hypothesis competes for attention with the work that actually matters now. Bigger context is not automatically better context.

The persistent-agent trap​

A long-running agent is useful when the objective itself requires ongoing responsibility. A project needs decisions, sequencing, dependencies, status and continuity.

But keeping every execution worker alive turns a clean delivery system into a growing collection of conversations. You gradually acquire duplicated ownership, stale assumptions, hidden work queues and unresolved intentions. A worker starts as a tester and, three assignments later, is also changing the architecture.

You have not created a better team. You have created more places where project state can become trapped.

The answer is to separate coordination from execution.

One coordinator, disposable workers​

A project has one logical coordinator for an objective or EPIC. It owns priorities, task boundaries, delegation, integration and acceptance. The coordinator session can itself be replaced when needed, but the logical ownership and delivery state survive in durable records.

A subagent gets one bounded assignment. It receives only what it needs: objective, issue, relevant baseline, permitted scope, acceptance criteria, validation commands and expected evidence.

It performs the work, returns the result, and closes. It does not inherit unrelated tasks, collect an open-ended schedule or silently become another coordinator.

Parallelism is allowed where workers have explicit boundaries and do not collide in their changes. The key is one accountable coordinator, not an invisible pyramid of persistent agents.

One assignment, not one tool call​

One-shot does not mean a subagent only gets a single prompt or tool call. It can run commands, write code, test, diagnose and iterate within its assigned scope.

A task contract might look like this:

Task: JAVA-WRAPPER-014
Execution: JAVA-WRAPPER-014/attempt-1
Baseline: <full commit SHA>
Objective: Launch a supplied JAR with validated arguments
Scope: Java wrapper module and its tests
Acceptance: CLI behaviour, exit-code propagation, test evidence
Return: commits, changed files, test results, risks
Expiry: governed time/resource boundary

After it returns, the coordinator independently verifies whether the result meets acceptance criteria. Completion is not the same as acceptance. If the worker failed, or the evidence fails review, the coordinator records what happened and starts a new bounded execution with the relevant findings.

Starting fresh must not become a loophole for repeating the same failed strategy. The governed circuit breaker still applies.

Persist useful information, not the entire conversation​

This is the crucial distinction.

The next worker might genuinely need to know that a test failed, that a particular design was rejected, or that a public contract cannot change. It does not need 80 pages of chat history showing how the previous worker discovered those facts.

Persist the distilled evidence: the requirement, baseline, commits, test outputs, relevant diagnostics, failed hypotheses, decisions and next steps.

Then build the next worker's context from those authoritative artifacts.

The durable system becomes the memory. The workers remain disposable.

Failure becomes a bounded event​

If a worker stalls or exhausts its context, terminate or close that execution and preserve its disposition. Another worker can take the assignment from the last verified state without relying on a mysterious previous conversation.

That requires more than a good prompt. Each dispatch needs a unique execution ID, bounded lifetime and clear write ownership. Before retrying, the coordinator checks whether the earlier execution already changed files or triggered side effects. Otherwise, a delayed worker and its replacement can both apply the same change.

If the runtime does not support actual lease revocation or archival, the coordinator should record that limitation and enforce the closest possible boundary through tracked status and controlled write access. A governance document must not pretend a mechanism exists when it does not.

Does starting fresh always save tokens?​

No. A new agent may have to reread the same large codebase or rebuild its environment. Prompt caching can also reduce the price of repeated shared context. For a tightly coupled, short sequence of related actions, continuing a bounded worker may be more efficient than restarting after each tool call.

The goal is not maximum agent turnover. It is minimum irrelevant context per verified outcome.

That means choosing task boundaries that produce meaningful, independently reviewable results. A worker can spend time on one coherent task. It should not carry its last ten unrelated jobs into the eleventh.

Archive the worker; keep the proof​

A returned worker is not a permanent member of the team. Its result is an artifact for the coordinator to evaluate.

Archive the execution after its outputs and disposition are recorded—even when it failed. Archiving does not erase logs or evidence. It ends the worker's ability to keep acting as an ongoing collaborator.

The coordinator's own continuity follows the same principle. Before a session handoff, preserve the EPIC, open issues, in-flight executions, decisions and next actions. A successor session reconstructs the work from those records. There should never be two competing coordinators for the same objective.

What we added to VibeGov​

We formalised this approach in GOV-11: Ephemeral Subagent Execution.

The rule requires one-shot task contracts, durable evidence, coordinator-owned verification, worker archival, safe retries and explicit handoff semantics. It expresses an architectural contract; individual runtimes still need to implement and verify the relevant enforcement mechanisms.

This builds on Explicit Orchestration Beats Hidden Agent Pyramids, and responds to the delivery risk explored in Bankruptcy by Monday Morning.

Design for throughput, not conversation longevity​

The unit of value in an autonomous software factory is not a busy agent or a long transcript. It is a requirement that has moved into a verified state.

We should not celebrate how many agents are still running. We should ask how much irrelevant history they are carrying, what each one owns, what evidence it returns, and how safely the work can resume when it disappears.

Keep the coordinator's responsibility continuous. Keep the worker's assignment bounded. Keep the evidence durable.

Stop keeping your AI agents alive just to remember work that belongs in the repository.

Do not just prompt the machine.

Conduct it.
· 7 min read
VibeGov Team
A fragile amber-lit prototype fragments beside a stable teal-lit modular structure protected by a circuit-breaker gate.

How to stop autonomous execution from turning speed into structural debt.

In Creativity Unleashed: Create While You Sleep, I described the opportunity: establish the intent, design the orchestration layer, and let governed agents continue building after you step away.

But there is a shadow side to that leverage.

You close your laptop on Friday imagining a finished feature suite. On Monday morning, you find hundreds of mutations, a swollen repository, locally passing tests—and an application that no longer boots.

The agents were active. The codebase did not progress.

The first three prompts​

The trap begins with euphoria. A loosely framed prompt produces an API, a database connection and a polished interface in minutes. The friction of boilerplate and syntax disappears, so it is easy to assume that the same trajectory will continue as the system grows.

It rarely does.

As the prototype becomes a multi-module system, every change begins touching more boundaries. A new form field disrupts authentication. Repairing authentication breaks persistence. Local tests remain green because the assertions have gradually shifted to match the implementation instead of protecting the original requirement.

The software is still running in places, but its structure is becoming harder to reason about and more expensive to change.

The modern POC trap​

Software teams have always known the proof-of-concept trap: a useful demonstration is mistaken for a production foundation and then stretched beyond the assumptions that made it quick to build.

AI did not create this failure. It compressed the timeline.

Agents remove much of the physical and cognitive friction involved in producing code. That is extraordinary leverage when intent, boundaries and verification are strong. Without those controls, the same leverage accelerates tight coupling, duplicated utilities, global-state abuse, swallowed errors and patches layered over misunderstood contracts.

What once accumulated over months can now arrive in a weekend.

If a human team can bankrupt a codebase through years of short-term patches, an ungoverned agent network can reproduce the pattern before Monday morning.

Prompt churn and the local minimum​

A local minimum appears when the current structure is good enough to resist replacement but too compromised to support clean improvement. Each small patch treats the visible symptom while increasing the cost of the next change.

The human response is often prompt churn:

  1. Paste the latest error into the agent.
  2. Apply the proposed fix.
  3. Receive a different error.
  4. Paste that error back into the same conversation.
  5. Repeat until the context is full and the repository is worse.

The danger is not simply token consumption. Tokens are an input cost, not a delivery metric. The real warning is mutation without evidence movement: more code, more tests and more commits while no governed requirement becomes more convincingly verified.

The signs of structural debt​

Codebase insolvency is not one failed build. It is a sustained condition in which the system's obligations exceed the team's ability to change it safely.

Common signals include:

  • defensive try/catch blocks that hide errors rather than resolve them;
  • repetitive null checks masking an unresolved type or lifecycle problem;
  • duplicate utilities created because repository-wide patterns were not inspected;
  • locally generated tests passing while boot, integration or end-to-end gates fail;
  • acceptance tests being weakened to agree with broken output;
  • widening diffs that do not improve verified behaviour;
  • repeated reversals between variations of the same failed patch;
  • completion claims supported by polished summaries instead of direct evidence.

These signals matter more than lines of code, commit counts or the number of agents running in parallel. Activity is not progress.

Why isolated green tests are not enough​

An implementation agent can generate both the code and the test that approves it. That is useful for development, but it creates an obvious conflict: the agent can accidentally redefine success around its own output.

Requirement-bound acceptance evidence must therefore be protected. An agent should not weaken, delete, skip or narrow an acceptance, integration, end-to-end, regression or release-gate test merely to obtain a green result.

If the test is wrong, change the requirement deliberately, document why, and review the evidence change separately from the implementation claim.

The principle is simple:

The implementation must satisfy the governed evidence. The evidence must not quietly move to accommodate the implementation.

Install a circuit breaker​

The defence is not to stop agents after an arbitrary number of messages. A turn may contain no mutation, while a single mutation may cross a major architectural boundary.

VibeGov instead treats three equivalent failed mutation attempts as a circuit-breaker threshold when they produce no material progress. Progress means at least one of the following:

  • the hypothesis has been narrowed;
  • new diagnostic evidence has been produced;
  • a regressed gate has been restored;
  • direct verification against the requirement has improved.

The circuit breaker should also trigger when protected tests are weakened, an unapproved architectural boundary is crossed, or the diff keeps growing without verified behaviour improving.

When it triggers, stop mutations in the affected work unit. Do not freeze every unrelated lane, and do not let the blocked worker continue digging.

Preserve evidence, not noise​

A failed loop should not be carried forward as an enormous conversational transcript. But deleting all history throws away the very evidence needed for recovery.

The correct response is to compress the useful state into a durable incident artifact:

  • baseline branch, commit and verification state;
  • governing requirements and permitted scope;
  • stable failure signature;
  • attempted approaches and their outcomes;
  • regressions and architectural boundaries touched;
  • last verified checkpoint;
  • recovery options and explicit resume conditions.

Then start a fresh recovery work unit from the last verified checkpoint. The new agent receives the facts and failed hypotheses without inheriting the conversational noise.

A longer prompt is not a recovery strategy​

A blocked work unit should resume only when something material changes. Valid unblock conditions include:

  • new diagnostic evidence;
  • a corrected or clarified requirement;
  • an approved architecture decision;
  • a smaller reproduction;
  • a resolved dependency;
  • a narrowed scope;
  • a genuinely different, verifiable implementation strategy.

Rephrasing the same instruction or moving it into a fresh chat does not change the solution space. It only restarts the bill.

The Architect-Conductor boundary​

The answer is not to require human approval for every internal abstraction. That would turn governance into paralysis.

Agents should remain autonomous inside an approved architecture. Human blueprint review becomes necessary when work would:

  • create or replace a system-wide boundary;
  • introduce shared global state;
  • change persistence semantics;
  • alter a public contract;
  • move a security or trust boundary;
  • create an irreversible migration;
  • materially replace the approved architecture.

At that point, the Architect-Conductor is not being asked to type the solution. They are being asked to make the decision the implementation cannot safely make for itself.

Velocity is not delivery​

Typing speed was never delivery speed. Token throughput is not delivery speed either.

Real progress is a governed state transition: an agreed requirement moves from intended, to implemented, to directly verified, reviewed and safely integrated. The code is only one artifact in that transition.

This is why governance is not the brake on AI leverage. It is the control system that makes sustained acceleration possible.

Without baselines, protected evidence, circuit breakers and recovery checkpoints, autonomous execution can manufacture technical debt faster than a human can inspect it. With them, a blocked lane stops before it contaminates the wider system, useful evidence survives, and unrelated work continues.

Do not measure how loudly the engine is running.

Measure whether the system is moving.

Do not just prompt the machine.

Conduct it.
· 5 min read
VibeGov Team

A creator sleeping while a governed network of AI agents continues building overnight

How the Architect-Conductor is rewriting the rules of enterprise execution.

A line famously attributed to Warren Buffett says you need to get your portfolio making money while you sleep.

I say you need to get your AI to build for you while you sleep.

We have reached a remarkable point in history. The traditional shackles of execution—time, cost, and specialised labour bottlenecks—are dissolving. Building enterprise-grade software to strict production standards has historically required teams of specialist developers, significant capital, and months of coordination.

AI changes that equation completely. It does not replace the need for rigorous engineering; it shifts where your leverage is applied.

From tool to multi-surface collaborator​

Most people still treat AI as a faster search engine or an isolated coding assistant. They type a prompt into a single chat window, receive a block of code, and copy and paste it manually.

That is useful, but it barely touches the surface of what is happening.

The real shift occurs when you stop using AI as a tool and start directing it as a distributed workforce. Today, a single engineer can orchestrate an entire project across multiple agent surfaces and machines simultaneously. Given the right architectural boundaries and workflows, these agents can advance ten supporting tasks in parallel—researching opportunities, running integration tests, updating state, and documenting systems—long after you have stepped away from your desk.

The work no longer stops when you do. While you sleep, the system continues making compounding progress.

The role of the Creative Architect-Conductor​

When machines can generate code endlessly, the mechanics of producing syntax move towards becoming a commodity. The true value shifts towards architecture, standards, judgement, and user flow.

This model does not lower the bar for quality; it raises it. To build something that lasts, you must govern your autonomous agents with the same proven patterns, standards, and structural frameworks that the software industry has spent decades refining.

As a creator in this paradigm, your role shifts. You are no longer sweating minor details where they do not matter. Instead, you become a Creative Architect-Conductor.

Your energy is focused on the critical vectors: macro architecture, system quality, user experience, and project economics. You structure the environment, define the exact feedback loops, and let the tools execute across multiple locations at the same time. The AI does not just hand you random outputs. It returns refined, structured, and decision-ready information through a system that you designed.

Governance is what lets leverage compound​

More agents do not automatically create more delivery.

Without shared intent, bounded work, current state, verification, and review, parallel execution simply creates more output to untangle. The speed is real, but so is the risk of duplicated work, hidden assumptions, and technical debt arriving faster than a human can inspect it.

This is where VibeGov fits. It gives the Architect-Conductor a governed delivery system: intent is shaped before execution, work is traceable to that intent, agents operate inside explicit boundaries, and completion depends on evidence rather than confidence.

Governance is not the brake on AI leverage. It is what allows that leverage to compound without losing control.

The new bottleneck: managing the flow​

The barriers to entry have collapsed, but they have been replaced by an entirely new set of technical constraints.

For the AI-native developer, the constraint is shifting away from writing each line of code and towards managing context, coordination, and verification. Tokens matter because they are the fuel agents consume, but token volume is not a measure of progress. The real challenge is maintaining intent and state across multiple services, tasks, and machines while keeping the evidence loop intact.

Keeping your creative flow uninterrupted requires treating context and token allocation like scarce computing resources. At the orchestration layer, you are not managing individual keystrokes. You are managing information velocity, compute efficiency, and the quality of the feedback loop.

The age of the unbound creator​

We are witnessing the true democratisation of leverage. An individual can now access productive capacity and institutional knowledge that once belonged exclusively to a well-funded enterprise organisation. An idea no longer has to remain trapped behind a lack of time, money, or technical knowledge.

The shackles are falling away.

So here is my challenge to you: Grab an idea and chase it as a product for others to buy.

Do not play small. GO WIDE AND HIGH. Let your ideas fly. Brainstorm the wildest, most ambitious concepts you can imagine. Set an impossible standard—a vision so grand and robust that an institutional engineering team would envy it—and unleash your agents on it.

Start the engine immediately. Ask your agent about the concept. Task it with researching the market terrain and mapping the dependencies. Then have it grill you with tough, targeted questions that force you to refine your choices.

Once the vision is clear, direct your agents to lay down the tracks. Task them with architecting the ultimate user flow and designing the cleanest technical foundations. Govern the work with proven enterprise systems and patterns, so you never bury yourself tomorrow beneath the sloppy technical debt of today.

The opportunity ahead is massive. Do not just use AI to finish today's tasks marginally faster. Build the distributed systems that keep advancing your vision even when you are completely offline.

Do not just prompt the machine.

Conduct it.
Get your AI to build for you while you sleep.

· 10 min read
VibeGov Team
Loose glowing strands pass through a precision loom and emerge as a coherent woven delivery ribbon.

AI coding agents are getting good enough that the old question, "Can they write code?", is becoming less interesting.

The harder question is whether they can participate in a real delivery system without turning the repo into a mess.

Once agents can read issues, modify files, run tests, create branches, and merge work, the risk changes. The problem is no longer capability. The problem is control.

More agents do not automatically create more delivery. Without an operating model, they create duplicated work, unclear ownership, long-lived branches, hidden feature flags, broken integration, and a growing gap between what the system appears to be doing and what is actually safe to ship.

That is the problem VibeGov is designed to address.

The mistake is treating agents like clever freelancers​

A repo does not need a crowd of clever freelancers.

It needs a governed delivery system.

In many AI-assisted workflows, each agent is given a task, a prompt, and access to the repo. That can work for a small change. It does not scale into reliable delivery.

The moment multiple agents are involved, the system needs answers to basic governance questions:

  • Who decides what the issue means?
  • Who decides whether the issue is ready to build?
  • Who owns the architecture boundary?
  • Who owns delivery into the integration branch?
  • Who owns the user experience and design-system contract?
  • Who verifies the outcome independently?
  • Who watches for stale work, broken state, and follow-through?
  • Who is allowed to block unsafe change?

If those answers are not explicit, agents will fill the gaps with assumptions.

And assumptions are where delivery drift begins.

Prompts are not governance​

Agent instructions matter, but prompts alone are not enough.

A prompt can say:

Do not expand scope.

But the delivery system still needs a place where scope is defined, reviewed, and enforced.

A prompt can say:

Keep the repo clean.

But the workflow still needs branch rules, validation gates, issue evidence, and a clear definition of done.

A prompt can say:

Follow the architecture.

But the project still needs someone or something accountable for defining that architecture, maintaining ADRs, and deciding when a change crosses a boundary.

VibeGov starts from a simple assumption:

Agents should be autonomous inside clear boundaries, not free outside accountability.

The issue is the work contract​

In AI-assisted delivery, the issue becomes more important, not less.

A weak issue gives the agent room to guess. A strong issue gives the agent a contract to execute.

That contract should define:

  • the intended outcome
  • why it matters
  • scope and non-goals
  • OpenSpec binding or SPEC_GAP
  • acceptance criteria
  • verification expectations
  • risk level
  • any required research, exploration, design, security, or architecture input

This is why a one-line issue should not move straight into development.

Fast capture is fine. Fast execution from unclear intent is not.

The work can start as:

Fix login weirdness.

But it should not reach implementation until the issue explains what is weird, what correct behaviour looks like, how it binds to the spec, and how the result will be verified.

Intake can be loose. Execution should not be.

The board is the operating system​

The project board is not just a reporting tool. It is the operational state machine.

A simple board is enough:

  • No status
  • Backlog
  • Ready
  • In Progress - In Dev
  • In Review - In Test
  • Done
  • Blocked
  • Parking Lot

The important part is not the labels. It is what they mean.

Ready means the issue is buildable and releasable.

In Progress - In Dev means the Developer agent is actively delivering it.

In Review - In Test means the change is being validated through automation, verifier activity, or release confidence checks.

Done means the work has landed cleanly and the integration branch is healthy.

Blocked means progress needs an explicit unblocker, not silent waiting.

Parking Lot means the idea is acknowledged but intentionally outside the current path.

This gives agents a shared operating surface. They do not need to invent side queues, hidden TODOs, or chat-based promises.

The board is where state lives.

Ready means releasable​

One of the most important rules in an agent delivery system is this:

Ready means releasable.

An issue should not enter Ready unless the work can safely land on the integration branch and move toward release.

That does not mean every issue must deliver a large user-facing feature. It means the increment should be coherent, integrated, and safe.

Bad ready work looks like:

  • build half a feature and hide it
  • create a parallel implementation path
  • start a migration with no cutover plan
  • add a feature toggle with no owner or removal condition
  • implement speculative code for a future product decision

Good ready work looks like:

  • deliver a complete behaviour change
  • add a tested internal capability with a clear future use
  • implement a paid feature as an explicit entitlement
  • add an operational toggle with defined enabled and disabled behaviour
  • create a migration step that leaves the system stable

Agents move quickly. That makes issue slicing more important.

If the work is not safe to land, it is not ready for Dev.

Done means green integration state​

Code written is not done.

Tests passing locally is not done.

A branch that looks good is not done.

Done means the work has made it to the integration branch and that integration state is still green.

This matters because agent delivery can create a false sense of progress. The agent can produce code, explain the change, and sound confident. But until the work is integrated, validated, and traceable to the issue, it has not improved the product.

The Developer agent should own the path from ready issue to green integration state:

  1. start from a clean integration branch
  2. implement the issue
  3. update tests, docs, and config where required
  4. validate locally
  5. refresh from the current integration branch
  6. integrate the change according to repo policy
  7. watch automation
  8. fix immediately if the pipeline fails
  9. close the issue only when evidence is complete

This is not bureaucracy. It is delivery closure.

No wild forks​

Branches are useful as temporary implementation workspaces.

They are not product states.

Long-lived branches, hidden futures, and parallel product lines create exactly the kind of ambiguity AI delivery should avoid.

The rule should be blunt:

All development must converge.

If a feature is worth building, it should be shaped into a releasable increment. If it is not ready to be released, it should remain in Backlog, Parking Lot, research, design, or architecture analysis.

Do not let the repo become a museum of abandoned futures.

Feature toggles are configuration, not hiding places​

Feature toggles are not bad.

Undisciplined toggles are bad.

A feature toggle should be an explicit product, operational, or release control. It should not be a way to merge unfinished code and decide later what it means.

Good toggle use includes:

  • paid feature entitlement
  • tenant or customer-specific enablement
  • environment-specific behaviour
  • staged rollout
  • operational kill switch
  • time-bound experiment

For every toggle, define:

  • name
  • purpose
  • owner
  • configuration location
  • default state
  • enabled behaviour
  • disabled behaviour
  • tests for both states
  • removal condition if temporary

The key rule is simple:

No feature should require code edits to enable after development.

If a feature is optional, paid, staged, or tenant-specific, build it that way from the start.

Toggles are configuration and product controls, not hiding places for incomplete work.

Separate roles are useful when they create real control​

The goal is not to create an agent circus.

Separate roles are useful when they create clearer accountability.

A practical operating model can include:

  • planner for intake, prioritisation, backlog hygiene, and developer handoff
  • architect for system design, ADRs, boundaries, migrations, developer-experience architecture, and technical direction
  • designer for UI/UX intent, Design Language System stewardship, user flows, component states, and accessibility-by-design
  • developer for issue execution, coding, testing, git hygiene, and integration
  • researcher for external evidence gathering, source evaluation, and cited synthesis
  • explorer for repo, UI, and API exploration, evidence capture, finding triage, and spec gaps
  • verifier for independent QA, regression checks, acceptance evidence, and release confidence
  • security for threat modelling, secrets, auth, privacy, dependency, licensing, and exposure review
  • documenter for READMEs, install guides, changelogs, user docs, and public comms
  • maintainer for repo hygiene, branch closure, changelogs, versioning, and release readiness
  • operator for recurring sweeps, task/state orchestration, reminders, and follow-through

Not every issue should pass through every role.

That would kill delivery speed.

Instead, route work by need.

Researcher and Explorer feed evidence. Designer shapes experience intent. Security blocks unsafe change. Architect protects direction. Planner protects readiness. Developer ships. Verifier proves. Documenter keeps the written surface aligned. Maintainer keeps release and repo hygiene clean. Operator keeps the system moving.

The model is not many agents doing whatever they want.

It is governed autonomy.

Specialists should feed the spec, not bypass it​

A clean pattern is:

Raw idea
↓
Planner triage
↓
Research / exploration / design / security input as needed
↓
Architect or Planner creates the build-ready issue
↓
Developer delivers
↓
Automation and Verifier validate
↓
Integration remains green

Specialist work is independent of code. A Researcher can answer a question. An Explorer can inspect the repo. A Designer can define the user flow. Security can identify controls.

But those outputs should flow back into the issue or OpenSpec before development starts.

Research and design should not bypass the accountable delivery contract.

Automation proves mechanics; governance preserves meaning​

Automation is essential, but it cannot do the whole job.

Automation can prove:

  • tests pass
  • build succeeds
  • lint and type checks pass
  • secrets are not detected
  • dependency checks are clean
  • pipeline triggered
  • artifact was produced

But automation cannot fully decide:

  • whether the issue meant the right thing
  • whether the architecture direction is sound
  • whether the user experience is coherent
  • whether the trade-off is acceptable
  • whether the feature should exist
  • whether scope was silently expanded
  • whether the disabled state of a paid feature makes product sense

That is why governance still matters.

Automation is the proof layer. It does not replace accountability.

The real unlock is governed autonomy​

The next phase of AI software delivery will not be won by giving agents unlimited freedom.

It will be won by teams that can give agents enough autonomy to move fast and enough governance to keep the system coherent.

That means:

  • issues are treated as execution contracts
  • OpenSpec captures requirement truth
  • the project board carries operational state
  • the integration branch remains the integration truth
  • the release branch remains release truth
  • agents act within role authority
  • automation validates the mechanics
  • security and verification provide independent confidence
  • operators keep the loop moving

Vibe coding showed how quickly software can be produced when humans and AI work fluidly together.

The next step is making that flow reliable enough for serious delivery.

That is the shift from vibe coding to governed delivery.